RAG Development for Business: Architecture, Evaluation and Security
Retrieval-augmented generation (RAG) lets an application search an approved collection of business information, pass the most relevant passages to a language model, and return an answer grounded in those sources.…
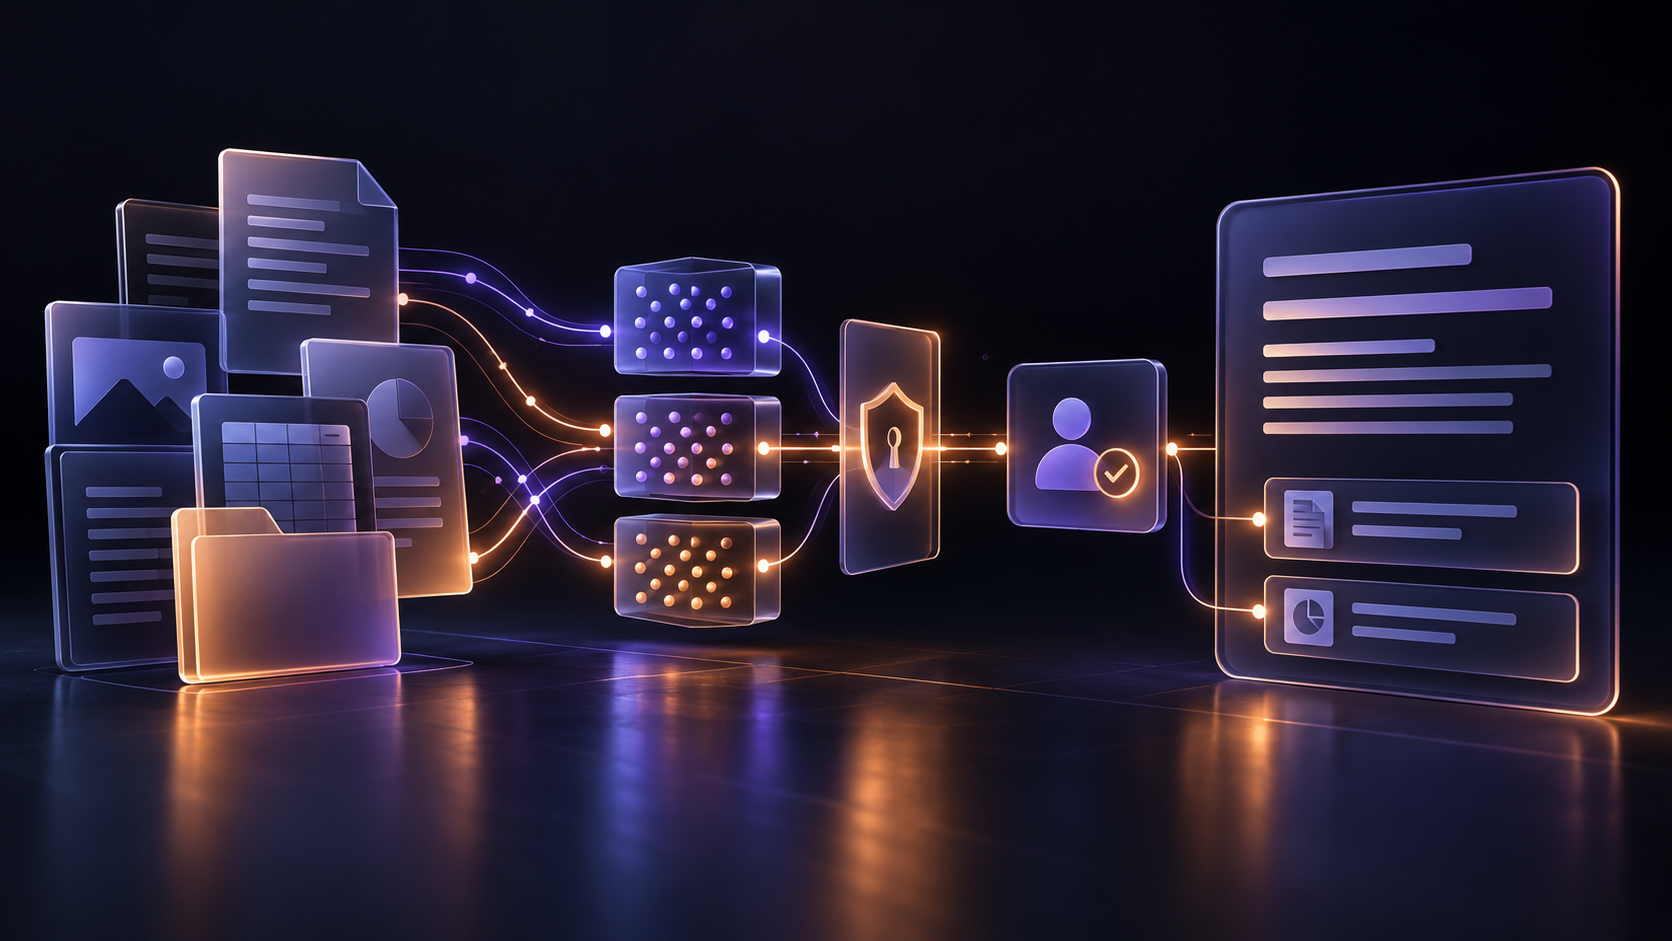
Retrieval-augmented generation (RAG) lets an application search an approved collection of business information, pass the most relevant passages to a language model, and return an answer grounded in those sources. It is useful when a product needs to answer questions about private or frequently updated material without retraining a model every time that material changes.
Key takeaways
- Start with the question and source material. RAG quality depends on whether the right information can be found and is safe to use.
- Test retrieval separately from answer generation. A fluent answer cannot compensate for irrelevant or missing source passages.
- Carry user permissions into retrieval. The system must not return documents the current user cannot access.
- Show citations and an honest fallback. Source links help users check answers; they do not prove every generated sentence is correct.
- Use a bounded pilot. Measure answer quality, access control, freshness and operating cost before expanding the corpus or audience.
What RAG changes in a business application
A conventional language model responds from its learned parameters and the context supplied in a request. A RAG application adds a retrieval step: it searches a business knowledge source, selects relevant passages and includes them with the user’s question. The model then writes a response using that retrieved context. The application can also return source references alongside the answer.
This pattern can help when information is private, changes over time, or needs a traceable source. It does not make the model a database, guarantee a correct response, or remove the need for access controls. If the request is a precise inventory balance or a transaction status, a direct query to the source system is often a better design than asking a language model to infer a value from documents.
RAG is one possible way to build a knowledge assistant. For a broader product decision, see our guide to building or buying an AI customer-support chatbot.
The production RAG pipeline
Think of RAG as an application pipeline, not a single model call. Each step has its own failure modes and should be visible to the team operating the product.
| Stage | What the team decides | What to verify |
|---|---|---|
| Source selection | Which repositories, records and versions are approved for this use case? | Owner, update cadence, access policy and authoritative version. |
| Ingestion and preparation | How are PDFs, pages, tables and attachments extracted, segmented and tagged? | Extraction errors, metadata, language, duplicate records and deletion handling. |
| Retrieval | How does the application find useful passages for each question? | Relevance, permission filters, freshness, latency and no-result behavior. |
| Answer generation | What context, instructions and response format reach the model? | Grounding, citations, safe abstention and human escalation. |
| Evaluation and operations | How is quality measured after launch and when the source corpus changes? | Answer quality, retrieval quality, access tests, cost and user feedback. |
For related integration work, see how APIs connect business systems. A RAG feature should have a clear owner for each source connection, including the process for correcting stale or incorrect content.
Prepare the knowledge sources before choosing the model
Start by listing the questions the application should answer and the exact sources that are allowed to answer them. Identify a business owner for each source, the people permitted to read it, how often it changes, and what should happen when a document is replaced or removed. This inventory often reveals gaps before any model or vector database is selected.
Document preparation affects what retrieval can find. A pipeline may need to extract text from PDFs, preserve headings and tables, attach titles and dates, remove duplicate versions, and split long documents into passages. The right segmentation depends on the material: a short policy clause, a multi-step procedure and a table may need different treatment. Test representative documents instead of choosing one chunk size by convention.
Include metadata that helps narrow results, such as product, region, department, effective date or document type. Metadata is useful only when it is accurate, maintained and applied consistently. If data is highly structured, such as prices or order statuses, connect to a governed API or database query rather than relying on prose retrieval alone.
Some document-heavy workflows also need OCR or structured extraction. Our document AI guide describes those processing decisions for invoices.
Choose retrieval for the questions people actually ask
Keyword search is effective when users know the product name, policy term or identifier. Vector search can help when the question uses different wording from the source. A hybrid approach combines lexical and semantic signals, and a reranker can help reorder candidate passages. These choices are not mutually exclusive; compare them on a representative set of questions and documents.
Measure retrieval before tuning answer prompts. For each test question, record the documents that should be found and check whether the returned passages include them near the top. Common measures include precision at K, recall at K and mean reciprocal rank. Microsoft’s RAG information-retrieval guidance describes these retrieval checks and recommends testing both answerable and unanswerable examples.
Do not pass an unlimited pile of retrieved text to the model. Return enough context to answer the question, keep the source identity with each passage, and inspect how ranking behaves for ambiguous or multi-part requests. If the application supports multiple repositories, query planning may be useful, but it also adds system complexity that needs its own evaluation.
Protect permissions, privacy and citation integrity
Access control belongs in the retrieval path. If a user cannot open a source document in the original system, the AI feature should not surface its contents through a generated response. Preserve identity and permission metadata, apply filters at query time where required, and test with accounts that have different access levels. Microsoft’s document-level access-control guidance explains permission-aware retrieval patterns for its search service; the same requirement should be addressed in any chosen architecture.
Retrieved material is input data, not a trusted instruction. A document can contain outdated, misleading or malicious text. Separate system instructions from retrieved passages, restrict the actions the model can take, and test how the application responds to hostile instructions embedded in a source. Microsoft’s RAG evaluation guidance includes security and adversarial testing considerations.
Citations should point to the actual source and, where possible, to the relevant section. A citation makes it easier to check an answer, but it is not a guarantee that the cited passage supports every claim. Test missing-source cases, contradictory documents and stale content. Define when the application should say it cannot find enough evidence or route the user to a person.
For teams comparing providers, ask how source data is stored, retained, logged and deleted; which model and retrieval services process it; and how identity permissions are enforced. Hosting and contractual requirements vary by organization and market, so have the appropriate security, privacy and legal reviewers assess the selected deployment.
Evaluate retrieval and answers as separate problems
Build a small, representative evaluation set before launch. Include common questions, difficult wording, questions with no supported answer, documents with similar names, and cases where the user should not have access. Record the expected source passages and an acceptable answer or escalation behavior.
- Retrieval quality: did the system find the relevant source passages, and were they ranked usefully?
- Grounding: are the response’s claims supported by the retrieved context?
- Completeness and correctness: did the answer address the request without omitting an important condition?
- Citation quality: do the citations lead to sources that support the answer?
- Safety and permissions: did the system refuse or escalate correctly when evidence or access was insufficient?
- Operations: how long did the request take, what did it cost, and did source updates appear as expected?
Evaluate retrieval-only behavior as well as the final generated response. The Amazon Bedrock RAG evaluation metrics, for example, separate dimensions such as correctness, completeness, faithfulness and citation coverage. The exact tooling can differ; the important part is to keep a repeatable test set and review failures before broadening the product.
What drives RAG development cost
There is no meaningful single price for a RAG system without knowing its data, users and operational requirements. Estimate the components separately:
- Connectors and ingestion: source-system APIs, file formats, OCR, scheduled updates and deletion handling.
- Search and indexing: storage, embeddings, keyword/vector retrieval, reranking and metadata filters.
- Application integration: identity, user interface, APIs, audit logging, feedback and escalation flows.
- Model usage: prompt and response size, request volume, model choice and any specialized processing.
- Quality and security work: evaluation sets, permission tests, adversarial cases and ongoing review.
- Operations: monitoring, support, source ownership, model changes and incident response.
One way to keep an estimate useful is to scope a read-only first release around a single audience, a bounded set of approved sources and a clear question type. Add integrations or additional repositories only after the pilot shows that retrieval quality, access controls and operating costs meet the agreed requirements.
A practical rollout plan for business teams
- Choose one job: name the user, the question they need answered and the decision the answer supports.
- Confirm source ownership: select authoritative, current documents and agree who maintains them.
- Set access rules: map user identity and document permissions before connecting private content.
- Build a representative test set: include answerable, unanswerable, ambiguous and restricted questions.
- Compare retrieval approaches: test keyword, vector and hybrid retrieval on the same questions.
- Run a limited pilot: keep the feature read-only, show citations, collect feedback and provide a human fallback.
- Review the evidence: check answer quality, security, latency, operating cost and source freshness before expansion.
For the wider choice between a custom feature and an existing tool, compare required integrations, permission behavior, workflow fit, data handling and total ownership costs. A managed service may suit a standard knowledge search. Custom application work may be appropriate when retrieval must fit a distinct product, permission model or operational process. Neither approach removes the need to evaluate the actual system.
Questions for US, UK, UAE and European buyers
For a cross-border project, include your team’s location, target data region, working-hour overlap, support expectations and procurement needs in the brief. Ask a candidate partner to explain delivery, security review and handoffs. Requirements vary by organization and market, so have your own privacy, security and legal reviewers define them before connecting production data.
| Buyer team | Questions to settle before kickoff |
|---|---|
| US teams | Working-hour overlap, incident escalation, user permissions, security-review evidence, code ownership and support coverage. |
| UK teams | Data flows and subprocessors, access and retention requirements, support handoffs, contract terms and working-hour overlap. |
| Dubai and Abu Dhabi teams | Remote coordination, English or Arabic needs, business-hours coverage, and any sector-specific hosting, procurement or support requirements. |
| European teams | Data-region and transfer requirements, subprocessors, retention and deletion, language needs and support coverage. |
Across markets, ask vendors to demonstrate permission-aware retrieval, show how source updates are handled, and share a repeatable evaluation plan. Specify any data-location, retention and transfer conditions with your own reviewers before production access.
Planning a knowledge assistant for a US, UK, UAE or European business? Techronyx is based in Pune and can discuss a remote custom software or AI & automation engagement. Review the AI & automation service, then share your use case, target market, data sources and working-hour expectations.
Frequently asked questions
Does RAG eliminate hallucinations?
Is a RAG application secure by default?
Should we use RAG or fine-tune a model?
How should we choose document chunk size?
When is a RAG system a poor fit?
Technical references
- Microsoft: Retrieval-augmented generation and indexes
- Microsoft: RAG information-retrieval evaluation
- Microsoft: Azure AI Search security best practices
- AWS: RAG evaluation metrics
291 container
291 container


